PointAction: 3D Points as Universal Action Representations
for Robot Control
TL;DR: PointAction jointly predicts future RGB frames and pixel-aligned XYZ pointmaps. The predicted robot-surface points provide a common geometric action interface, which an embodiment-specific decoder translates into robot controls.
Abstract
World Action Models (WAMs) leverage the broad visual dynamics captured by pretrained video diffusion models, offering a promising path toward generalizable robot manipulation. However, RGB-only rollouts leave 3D motion and fine-grained spatial constraints implicit, making action grounding ambiguous. Meanwhile, scaling action supervision across tasks and embodiments remains costly. We present PointAction, a framework that uses dynamic 3D points as an action interface between video prediction and robot control. PointAction adapts a foundation video model to jointly predict future RGB frames and dynamic 3D pointmaps. This interface expresses proposed robot motion in a common geometric form, which an embodiment-specific diffusion decoder translates into controls. Geometric supervision from videos enables the rollout model to learn beyond paired action data, while target-robot video adaptation and decoder training support transfer with limited demonstrations. Experiments demonstrate strong 4D generation quality on robot scenes, competitive manipulation performance in simulation, and adaptation to two real robot arms unseen during pretraining. These results support 3D point dynamics as a common representation for connecting video prediction to robot control.
Method Overview
PointAction factorizes video-to-action learning into a shared video-to-point model and an embodiment-specific point-to-action decoder. Initialized from Large Video Planner (LVP), the generator jointly predicts full-scene RGB and camera-frame XYZ pointmaps through width-wise latent concatenation. SAM 3 masks select the predicted robot-surface points, and a conditional diffusion decoder translates their motion into controls using the initial robot state. The points are per-frame surface samples, so no persistent point tracking is needed. For a new embodiment, target-robot videos adapt the generator and paired demonstrations train the decoder.
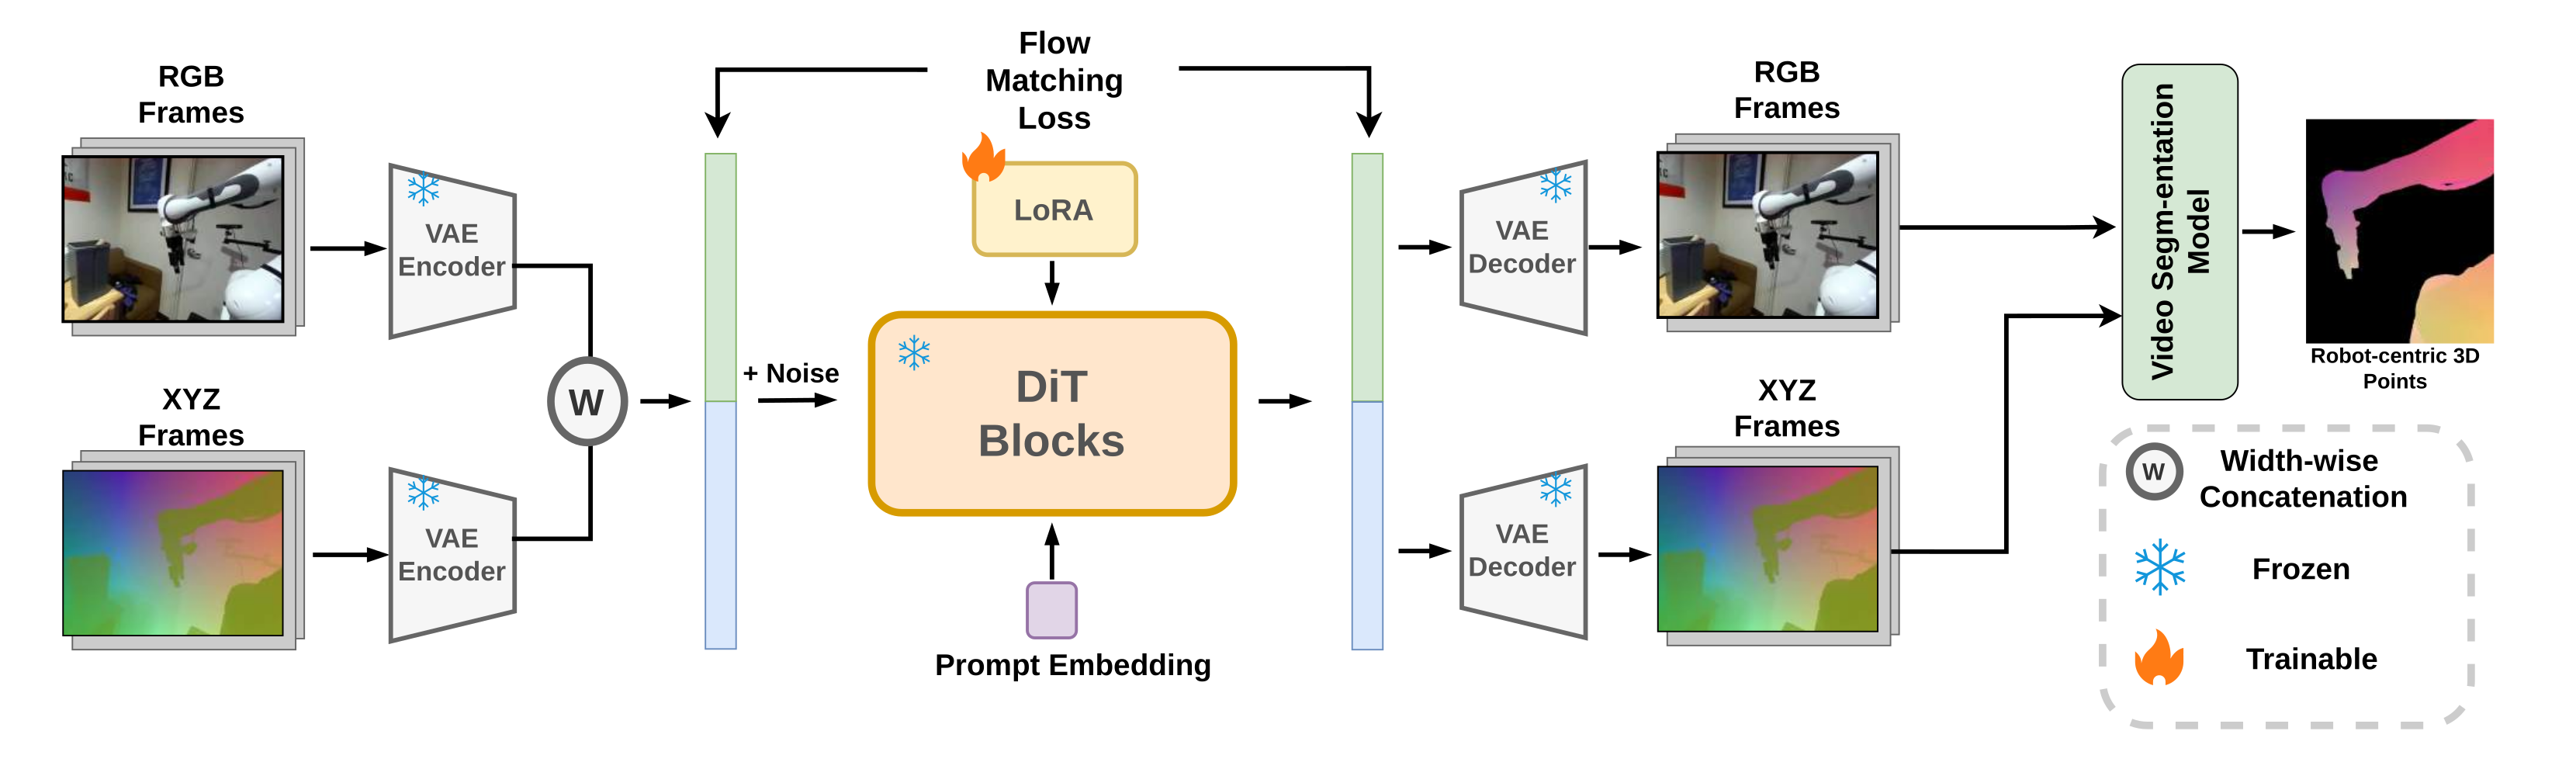
Stage 1: Joint RGB-XYZ Prediction. A foundation video diffusion model is lifted to jointly generate RGB and XYZ pointmaps by concatenating their VAE latents along the width dimension. We train with a flow-matching objective under diffusion forcing on cross-arm robot videos.
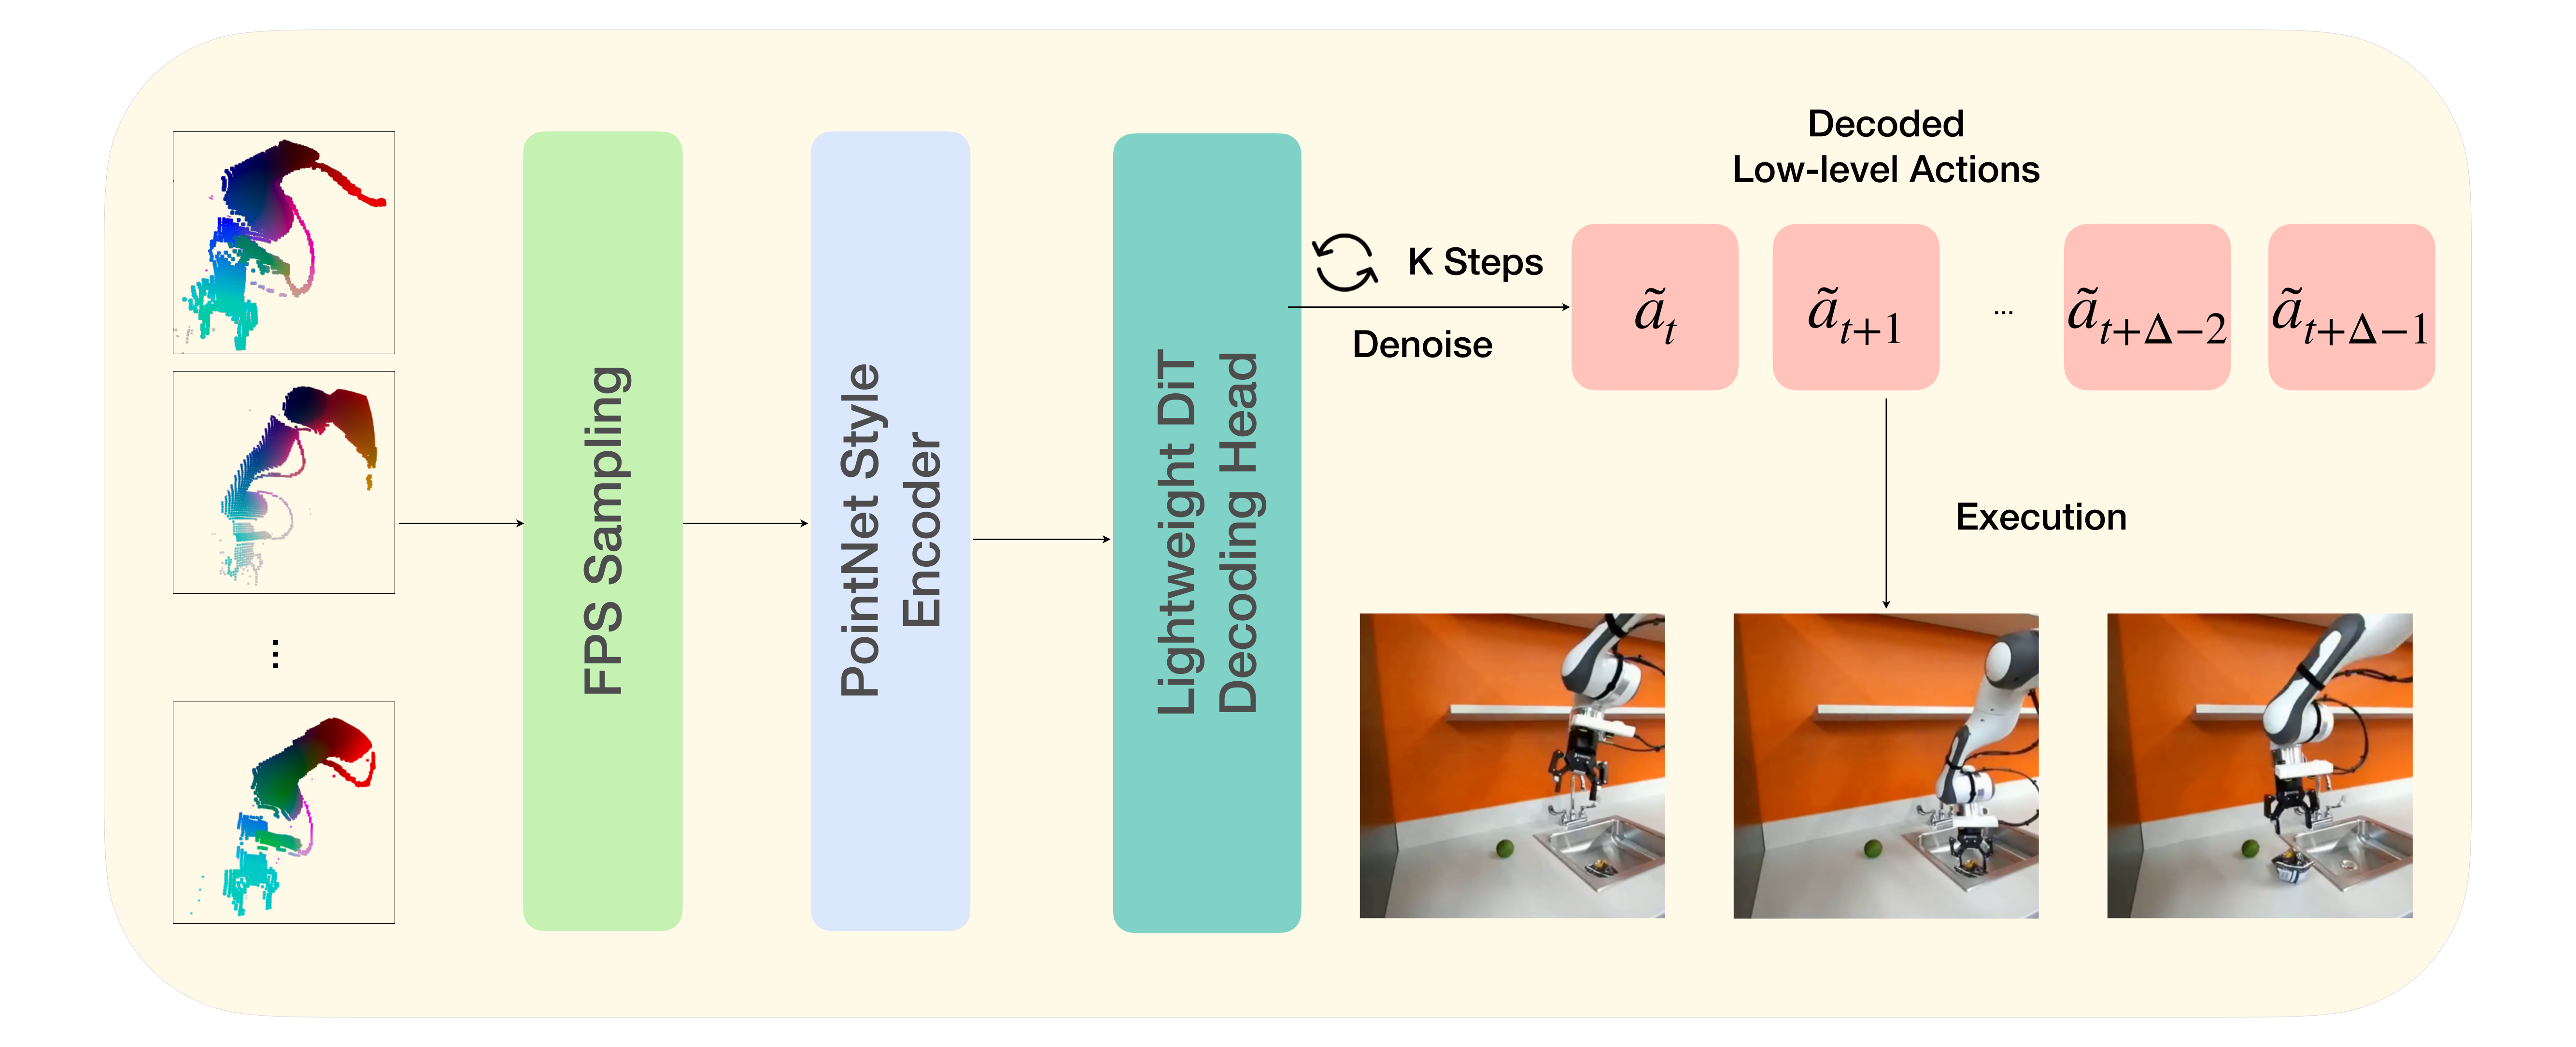
Stage 2: Point-to-Action Decoder. Robot-centric point clouds are downsampled with FPS, encoded by a PointNet-style MLP, and fed into a thin conditional DiT that denoises the action sequence in parallel.
Interactive 4D Generation Viewer
Drag, zoom, and replay our jointly generated RGB frames and evolving 3D point clouds directly in your browser. The four scenes below are drawn from DROID and BridgeData V2, the two datasets we pretrained our 4D video model on.
Underlying generated video and 3D point map for the selected scene (RGB | pixel-aligned XYZ pointmap)
Real-Robot Demonstrations
PointAction adapts to two robot arms unseen during pretraining, xArm7 and YAM, reaching 43.0% and 43.3% mean success, compared with 22.7% and 11.7% for the strongest VLA baselines. Both settings post-train the generator for 500 steps and train an embodiment-specific decoder, using 50 demonstrations per task on xArm7 and 20 on YAM, with 100 and 20 evaluation trials per task, respectively. The clips below show two example rollouts per task.
Task
Take
Execution setting. Each predicted rollout is decoded into a 49-step action sequence and executed open-loop. Planning takes about 381 seconds per sequence and is not shown in the videos.
4D Generation Quality
The action decoder relies on temporally and geometrically consistent 4D rollouts from the upstream World Action Model. Below are qualitative rollouts on held-out trajectories from DROID and BridgeData V2, visualizing RGB frames, predicted XYZ pointmaps, and the pointmaps rendered as 3D point clouds across four timesteps.
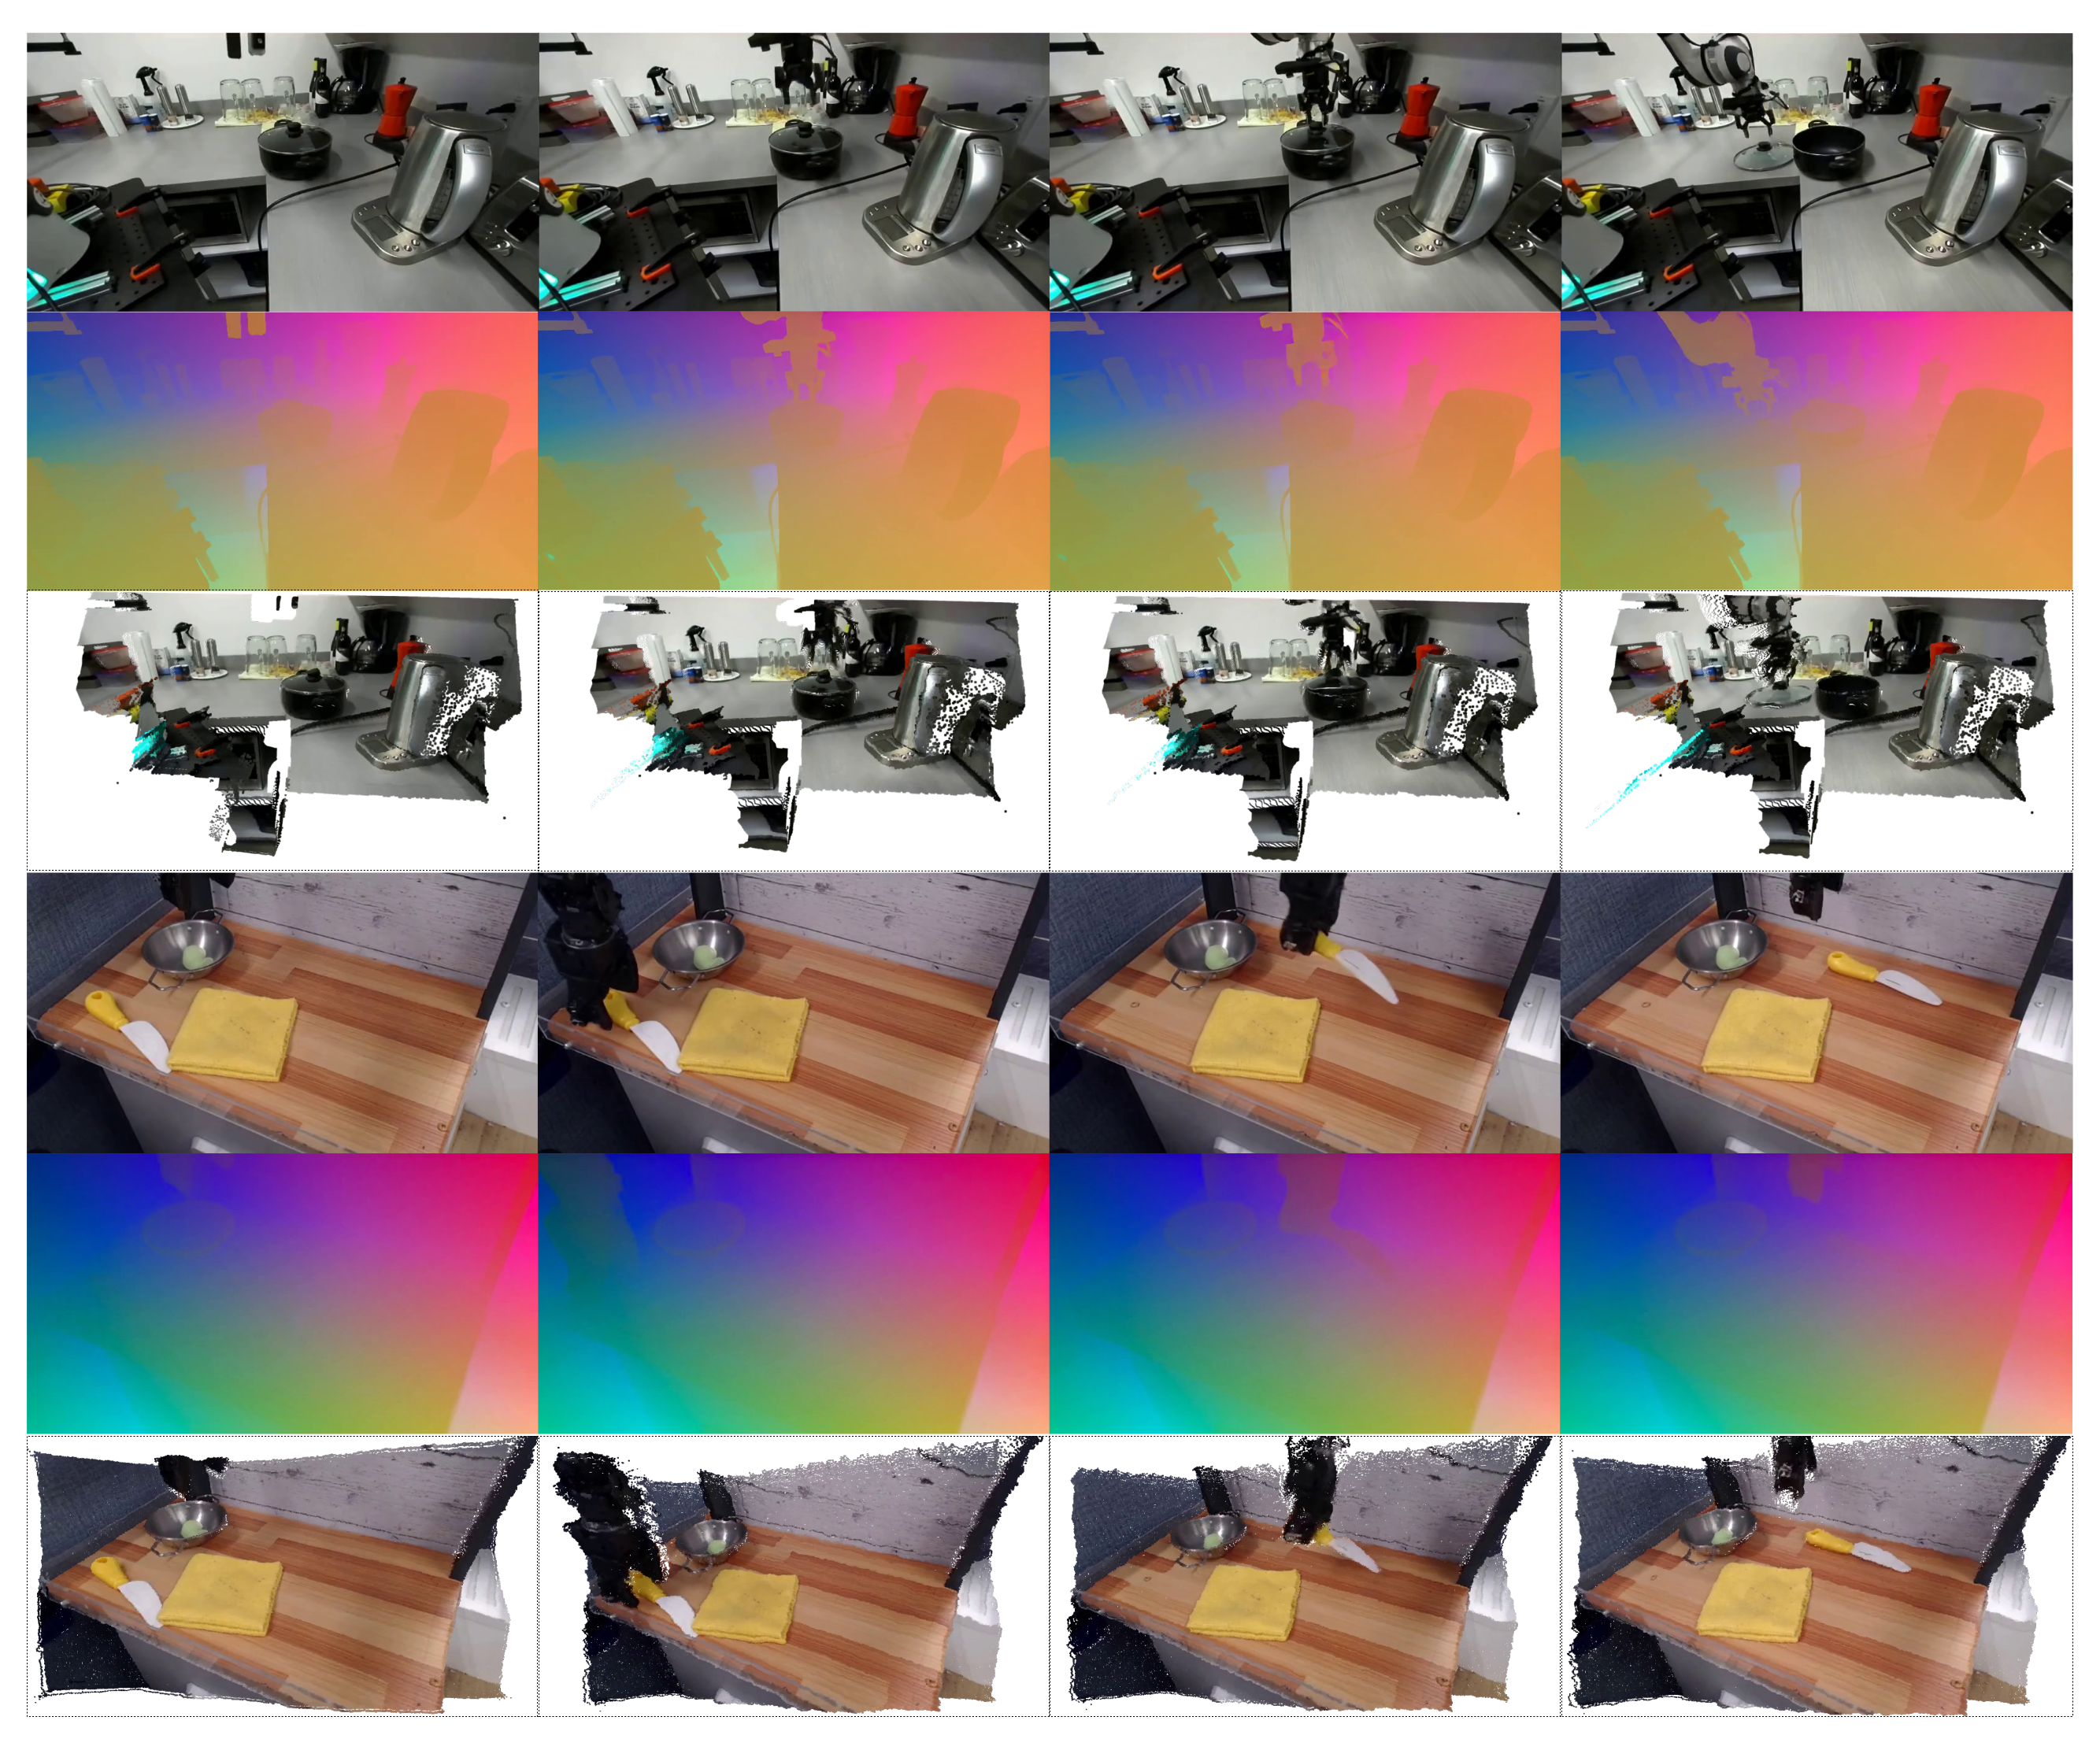
Qualitative 4D generation by PointAction on real-world rollouts. Top: a held-out trajectory from DROID; bottom: a held-out trajectory from BridgeData V2. Columns are four uniformly sampled timesteps. Rows: (a) generated RGB frames, (b) generated XYZ pointmaps, (c) rendered XYZ as a 3D point cloud.
Simulation on RoboCasa365
On RoboCasa365, PointAction achieves the highest success rate in all three regimes, ahead of GR00T N1.7, π0.5, VPP, Cosmos Policy, and ATM under a shared single-view protocol. ID and OOD-Env average ten seen tasks; OOD-Task averages five unseen tasks.
| Method | ID | OOD-Env | OOD-Task |
|---|---|---|---|
| ATM | 24.3 | 5.6 | 0.0 |
| GR00T N1.7 | 44.5 | 37.6 | 8.6 |
| π0.5 | 39.8 | 35.2 | 6.8 |
| VPP | 34.5 | 32.2 | 7.4 |
| Cosmos Policy | 45.2 | 42.9 | 14.0 |
| PointAction | 47.7 | 44.1 | 17.0 |
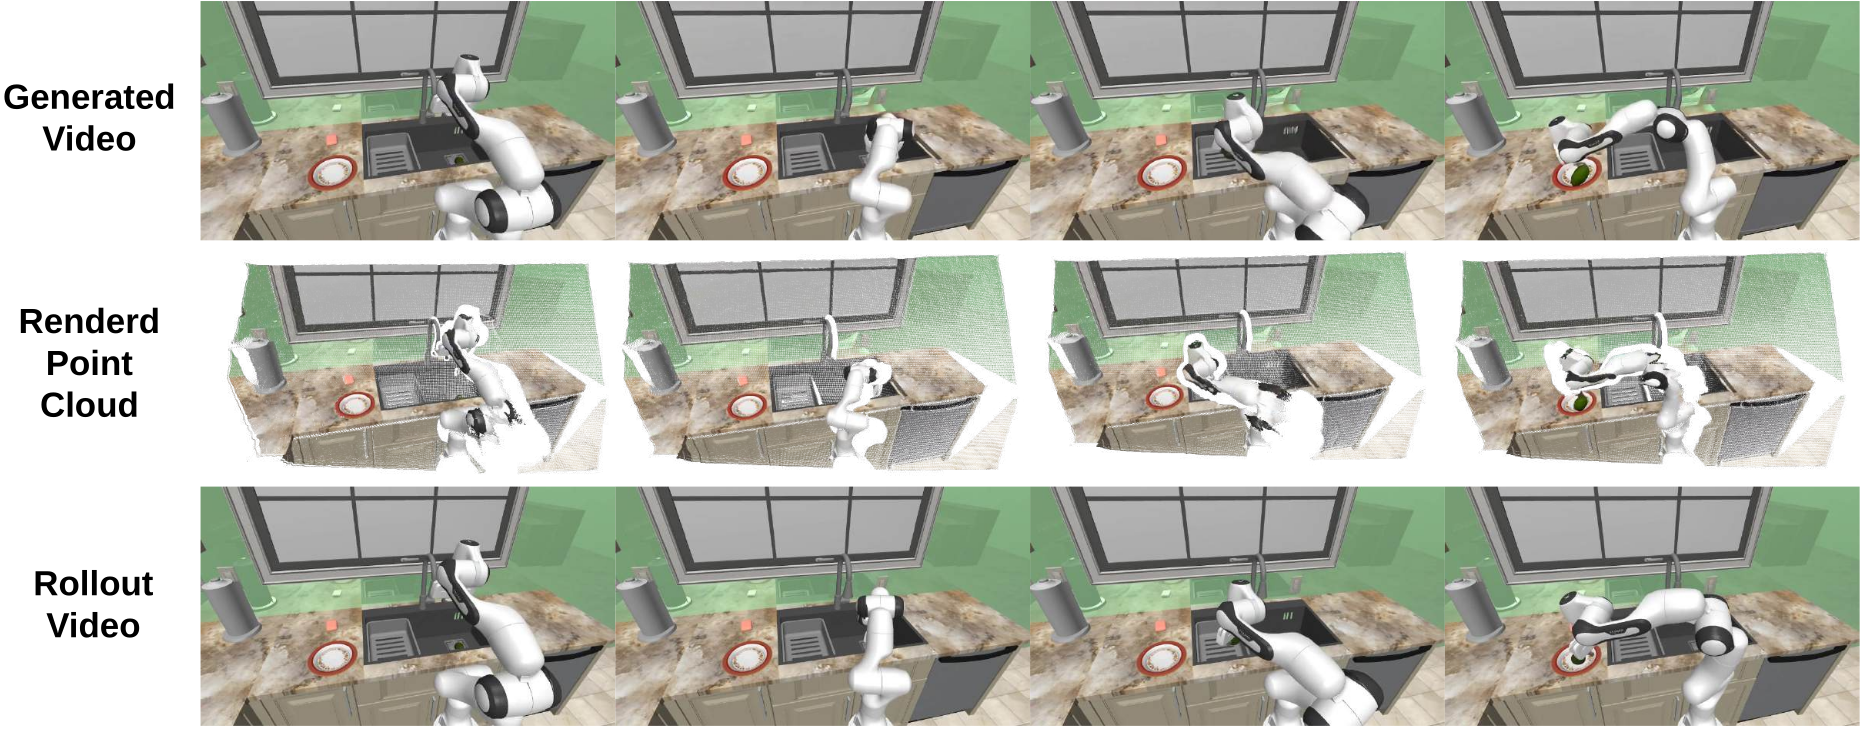
Qualitative rollouts on RoboCasa365. Columns show successive timesteps. Rows show generated RGB frames, rendered predicted point clouds, and actual robot execution.